Six official reports and one practitioner write-up, all dated October 6, cover agent evaluation, enterprise integration, models and research verification. Selection uses verifiable sources within 48 hours and was checked against 17 stories in the prior two editions. This is editorial source selection, not a comprehensive news ranking.
Summaries condense the sources into Traditional Chinese with corresponding English. They contain source-supported facts and attributed author views, without newsletter commentary. The target is about 500 Chinese characters; entries are shorter when evidence or source-use limits require it. Configured RSS collection was incomplete, so this edition uses direct primary-source selection.
No matching picks. Try another keyword or reset the filters.
Illustration unavailable
AI-generated concept illustration | A computer displays a contract approval workflow beside a cursor and checklist magnifier. Not an actual product screenshot or event photograph.
OpenAI and Ironclad evaluated 11 contracting workflows with 8–50 criteria each. Tasks cover nondisclosure agreements, procurement approvals and jurisdiction-dependent clauses. GPT-6 Astra (Max) averaged 55.0%, versus GPT-5.6 Sol (High) at 41.6%; estimated attempt times were 19.2 and 37 minutes. OpenAI says timings were simulated from assumed speeds, not measured customer savings.
Shorter summary: limited to verified source material and permitted condensation.
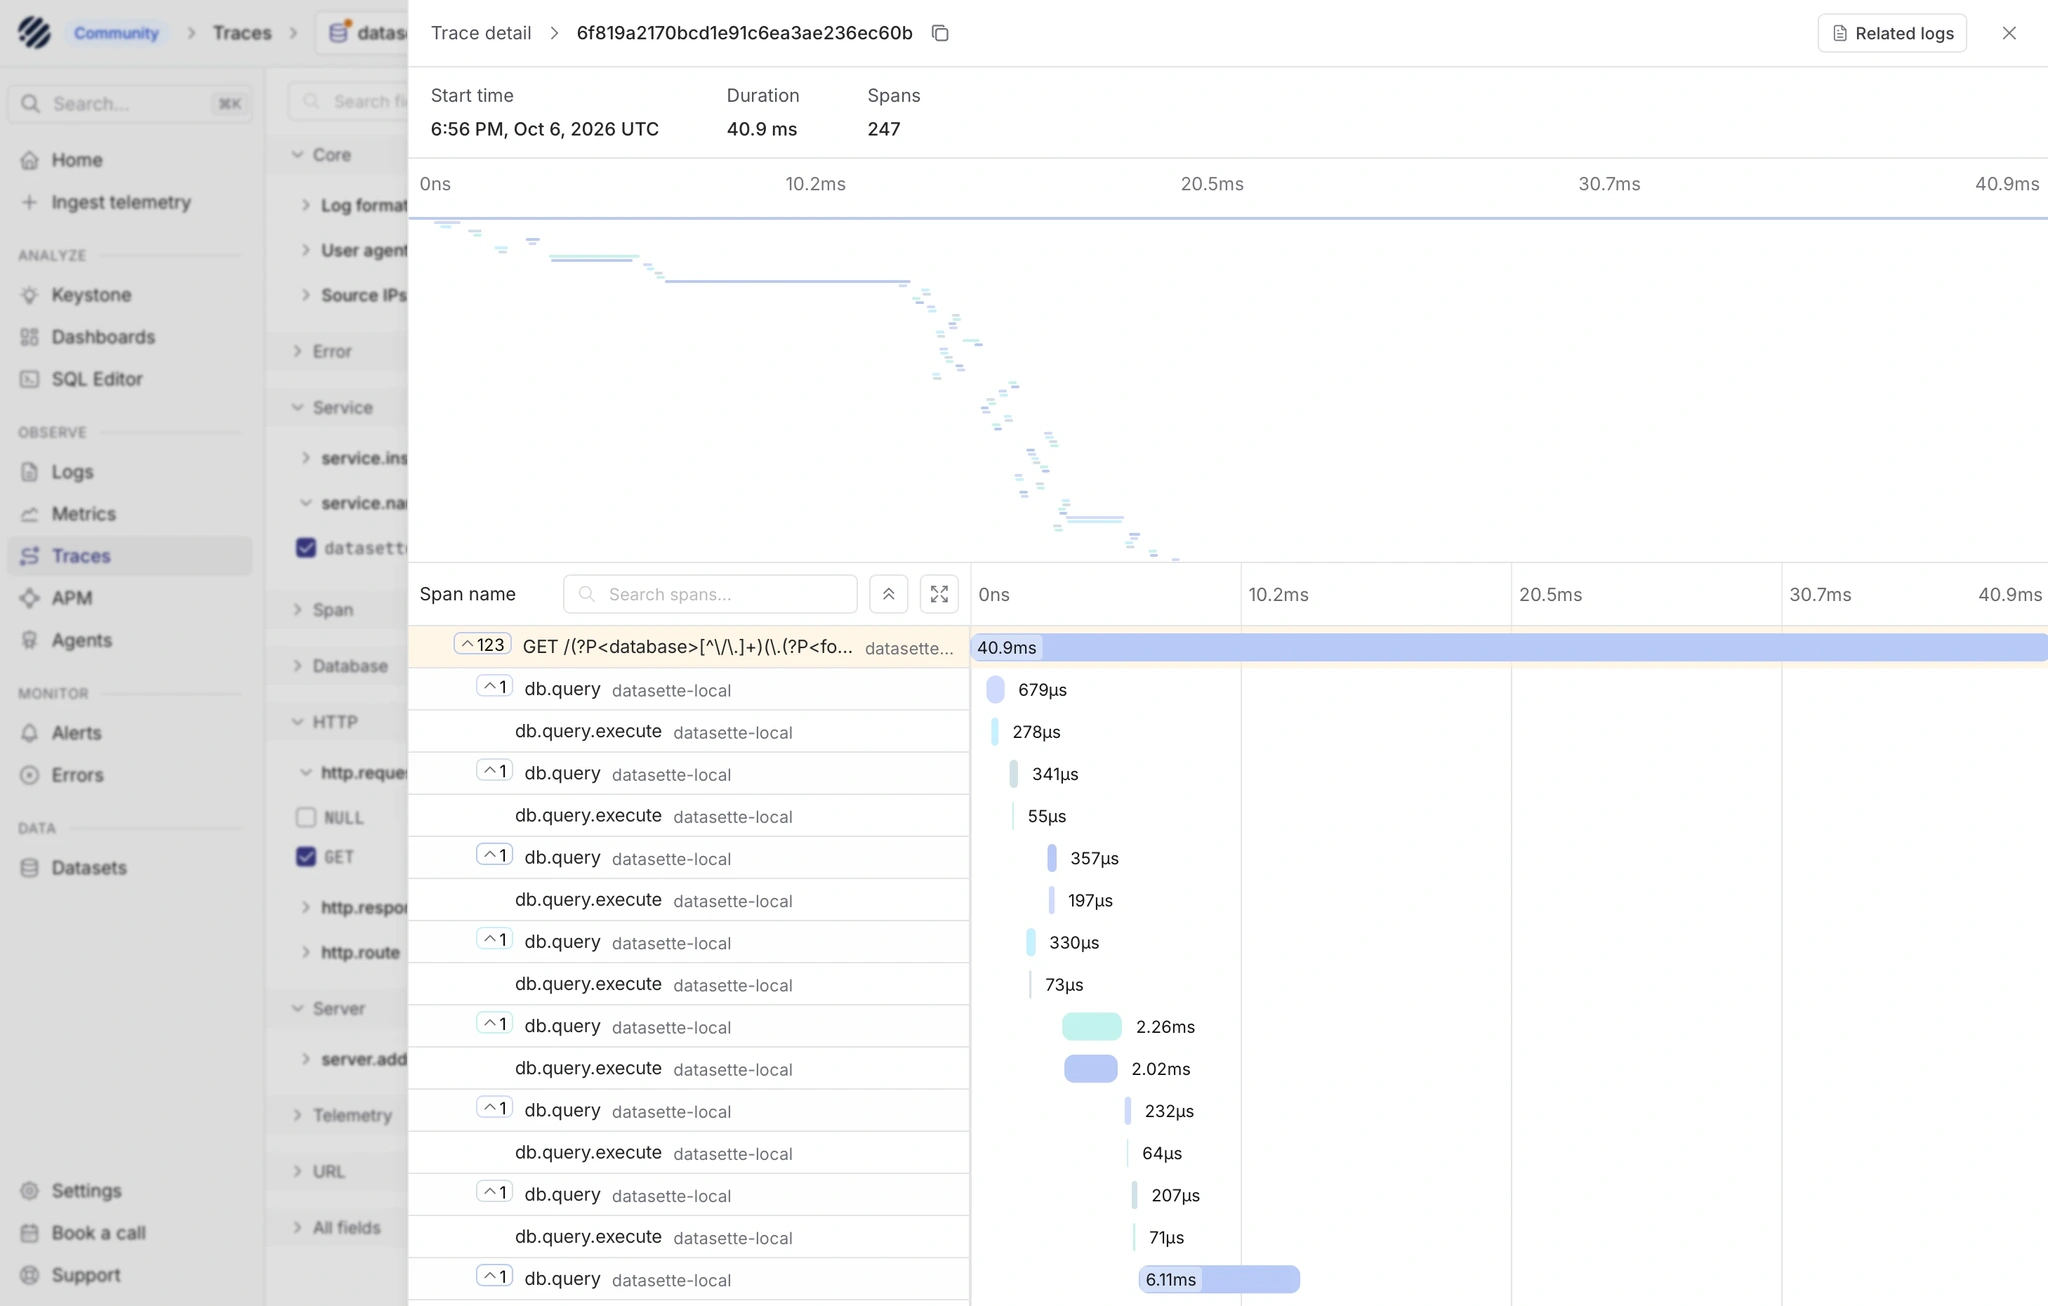
On October 6, Simon Willison said he asked Codex to work out how to run Parseable and receive Datasette traces, then wrote the working instructions himself.
His local example uses Parseable 3.2.4 with Datasette 1.0a41, local storage, an exporter endpoint, a service name and a stream. After browsing Datasette, Parseable displays requests and their SQL-query traces; the notes also give alternate-port settings. Parseable defaults to ports 8000, 8001 and 8002; changing them also requires updating Datasette’s exporter endpoint.
Datasette’s changelog dates OpenTelemetry support to September 24, covering HTTP requests, database queries and startup, with metrics including query latency and write queues. Official documentation requires launching through opentelemetry-instrument: direct Datasette startup produces no telemetry, and the default batch processor exports every five seconds. The documentation adds that omitting OTEL_SERVICE_NAME files traces under unknown_service, and shutdown flushes the final batch.
AI-generated concept illustration | Documents connect to a knowledge hub as three abstract people move a project card together. Not an actual product screenshot or event photograph.
On October 6, Atlassian and OpenAI expanded their partnership to power agents in Rovo and Atlassian’s platform with OpenAI models and Teamwork Graph context connecting people, projects, documents and decisions. OpenAI reports that over 3,000 Atlassian developers use Codex in terminals, editors and code review. The agreement extends a collaboration begun in 2023 and expands Atlassian’s access to OpenAI frontier models.
Atlassian lists MCP-based enterprise context as available now; autonomous work pickup, test execution, session synchronization and multi-agent orchestration remain design plans with human checkpoints. The announcement also lists DX as a currently available tool for observing developer impact. It describes recording requirements, agent progress and decisions in Jira.
The existing plugin announcement describes selecting Jira work, Confluence content or people in prompts, plus a pinned Home for resuming work. Home gathers assigned Jira work, recent Looms, projects and Bitbucket pull requests awaiting review; selecting an item opens a conversation with a prefilled prompt. That page says access remains subject to the user’s Atlassian permissions and organizational controls.
Source highlight
MCP-based enterprise context is available
Caveats & dates
Deeper autonomous-agent integrations remain in design
AI-generated concept illustration | Three verification gates, a key and an inspection lens protect a server. Not an actual product screenshot or event photograph.
Anthropic divided CVP into Defense, Red Team and Specialized Access. Defense covers incident response and vulnerability analysis; Specialized Access is reserved for a limited set of organizations authorized to test high-risk safety systems. Its Opus 5.5 evaluation ran five attempts on ten scenarios: Defense blocked 46 trials; Red Team blocked none and completed 34. Red Team currently admits organizations only and permits testing solely on authorized systems.
Separate official security requirements mandate an actionable security contact, prohibit shared sign-ins and require enabled user profiles so requests are attributable to named users or workloads. Anthropic may request continuing evidence of compliance with those requirements. Suspected breaches or misuse involving CVP access must be reported to Anthropic within 72 hours, or within 24 hours for a security incident.
Shorter summary: limited to verified source material and permitted condensation.
AI-generated concept illustration | A phone connects image, audio, text and video cards to a shared geometric space. Not an actual product screenshot or event photograph.
Google released Apache-2.0 EmbeddingGemma 2 with 740M parameters, a 270M text-only configuration and optional vision and audio encoders. The announcement lists 768-dimensional output, reducible to 512, 256 or 128 dimensions. Google reports that quantized weights on Pixel 11 Pro use as little as roughly 191MB active RAM for text-only and 567MB for the full model.
The official product page describes a shared embedding space for text, images, video and audio, supporting cross-modal search and RAG retrieval with an 8K-token context. Its examples include finding images with text and video moments with voice memos; it lists audio inputs up to 5.5 minutes.
Shorter summary: limited to verified source material and permitted condensation.
Source highlight
Vision and audio encoders are optional
Caveats & dates
Published memory figures use quantization and specified hardware
AI-generated concept illustration | A modular cube on a test platform with abstract code, a CAD shape and a comparison lens. Not an actual product screenshot or event photograph.
Mistral’s October 6 changelog announces Large 4 in public preview. It describes a general-purpose multimodal mixture-of-experts model with a one-million-token context, while saying open weights are still forthcoming.
Shorter summary: limited to verified source material and permitted condensation.
AI-generated concept illustration | Mathematical sketches pass through a transparent verification frame into reasoning nodes. Not an actual product screenshot or event photograph.
OpenAI released internal-model mathematical results, including many Lean formalizations, ten reasoning summaries, attempted-problem counts and compute estimates. The company estimates average compute per result equivalent to roughly three hours of ChatGPT Pro thinking and plans further formalizations. The announcement also provides paper-revision and citation procedures.
In its same-day statement, independent advisory group AGMAI said its role neither judges the results’ impact nor endorses OpenAI’s production process. The group considers release the beginning of human understanding and incorporation into mathematical knowledge, with assessment belonging to the mathematical community.
AGMAI’s September 29 recommendations call for model, prompt, reasoning-summary, time and compute-cost disclosure, explicit formalization status, and explanations of problem selection and failed attempts at comparable problems. The group also advocates lab funding for human understanding while keeping those activities community-led.
Shorter summary: limited to verified source material and permitted condensation.
Source highlight
The release includes attempted-problem counts and compute estimates
Export the settings, then run the collector to discover new articles. This page only previews configuration; it does not save server settings or change published editions.
Running a search sends keywords to GDELT and arXiv. Do not enter private information. GDELT uses an English index; supply your own English aliases for Chinese topics.
 Illustration unavailable